Most "winning" A/B tests never reached real significance, stopped early because the numbers looked good, or run on too little traffic to mean anything. We calculate sample size before launch and report a null result honestly when that's what the data shows.
CRO built on tests that actually reach significance
The problem, reframed
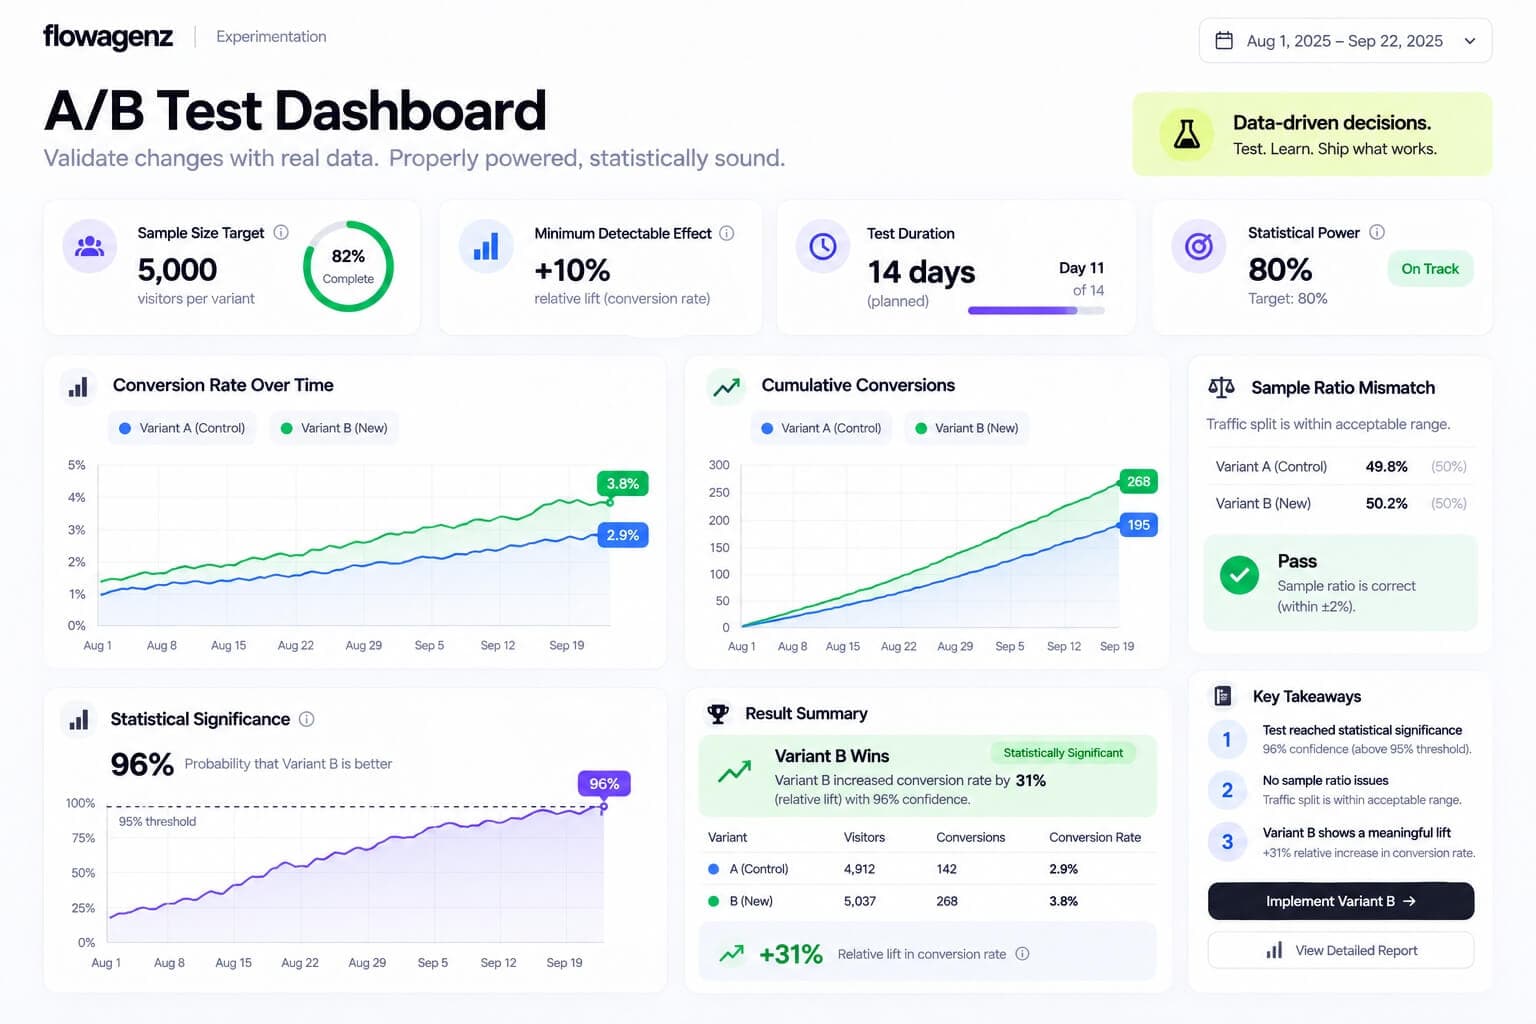
A test stopped the moment it starts looking significant, rather than run to its pre-calculated sample size, has a meaningfully higher chance of being a false positive than the reported confidence level suggests. A test run on a low-traffic site for two weeks, declaring a 20 percent lift, often never reached the sample size needed to detect that lift reliably in the first place. And a sample ratio mismatch, the actual traffic split landing meaningfully off from the intended split, is a real technical failure mode that invalidates a result and gets checked on almost no CRO engagement outside dedicated experimentation teams.
None of this means testing doesn't work. It means most of what gets reported as a "win" in this industry is closer to a good guess dressed up with a confidence percentage. We would rather run fewer, properly designed tests and tell you honestly when a result isn't real than hand you a stream of "winning" variants that don't hold up on a second look.
What we build
01
Funnel and behavior analysis before any hypothesis.
Session recordings, heatmaps, and funnel drop-off data reviewed first, so what gets tested is grounded in where users are actually struggling rather than a guess about what might move the needle.
02
Properly powered test design.
Sample size and minimum detectable effect calculated from your real baseline conversion rate and traffic volume before a test launches, so a result that reaches significance actually means something. Sample ratio mismatch checked on every test, not assumed away.
03
Test implementation at the code level.
Because we build the sites ourselves, on Next.js, WordPress, and Shopify, we implement test variants directly in code rather than through a client-side script injecting changes after the page loads, which causes the layout flicker and performance hit that plagues most no-code testing tools and can itself distort results.
04
Testing calibrated to your actual traffic.
Low-traffic B2B sites need bigger, bolder variant swings and down-funnel metrics, demo requests, qualified leads, pipeline, tracked instead of raw clicks, since there usually isn't enough volume to detect a small button-color change reliably. Higher-traffic e-commerce sites can run more granular, iterative tests where that volume actually supports it.
05
Qualitative research alongside the numbers.
User testing and on-site surveys paired with the quantitative data, because a test tells you what happened, not why, and the why is what makes the next test better than a guess.
06
Honest reporting, including null results.
A test that didn't reach significance is a real, useful finding, it tells you the hypothesis wasn't right or the effect wasn't big enough to matter. We report that plainly instead of quietly moving on to the next test and letting the last one disappear from the conversation.
Built on real engineering, not a script injected after the fact
Because we build the underlying sites, test variants ship as real code changes rather than a third-party script rewriting the DOM after page load, which avoids the flicker and load-time penalty that can itself suppress conversion and quietly bias a test's results.
Who this is for
01
Businesses whose current CRO program keeps reporting wins that don't hold up,
tests stopped early or run without enough traffic to mean anything.
02
B2B companies with lower traffic volume
who need down-funnel metrics and bolder test variants instead of micro-optimizations measured on clicks that never reach significance.
03
E-commerce brands
wanting real funnel and checkout optimization grounded in behavior data, not a guess about what might convert better.
04
Teams tired of being handed a stream of "winning" variants
with no visibility into whether the underlying test was actually valid.
Why Flowagenz
Test results and data you own outright.
All testing data, session recordings, and results live in your own analytics and testing tools. No dependency on a Flowagenz-run dashboard to see your own numbers.
Based in Salem, Tamil Nadu.
Western-grade CRO and engineering work at a rate structure offshore delivery makes possible.
Real overlap, not vague promises.
Async-first communication with working hours that overlap US Eastern mornings, UK afternoons, and Australian business hours on the same day.
We will not report a win that isn't real.
A false positive costs you an implementation decision built on noise. We calculate sample size before launch, check for sample ratio mismatch, and tell you honestly when a test didn't reach significance rather than declaring a winner to keep a report looking productive.
How it works
01
01
Behavior and funnel audit.
Session recordings, heatmaps, and drop-off analysis reviewed to identify where users are actually struggling, grounding hypotheses in real behavior rather than guesswork.
02
02
Test design and power calculation.
Sample size and minimum detectable effect calculated from your actual traffic and baseline conversion rate, so the test is designed to reach a real answer.
03
03
Code-level implementation.
Variants built directly into the site rather than injected by a third-party script, avoiding the flicker and performance cost that can distort results.
04
04
Honest measurement and reporting.
Results reported against the pre-calculated significance threshold, with sample ratio mismatch checked and null results stated plainly. Timeline to a valid result depends entirely on your traffic volume and baseline conversion rate, a low-traffic B2B site may need a bolder test running longer than a high-traffic e-commerce funnel testing a smaller change.
FAQ
Frequently Asked Questions
Everything you need to know about our process and digital systems.
No, and any agency promising a specific lift before seeing your traffic and baseline data is making a number up. We commit to properly designed tests that reach real answers, and we report honestly whether that answer is a lift, no meaningful difference, or a result that needs a bigger sample to confirm.
Ready for tests that actually mean something
Tell us what your current conversion funnel looks like and what your traffic volume is, and we will scope the audit and the testing program on a short call.