Advisory work for teams with their own developers who want a second set of eyes: architecture review, scaling guidance, a governance audit of workflows nobody has revisited since the builder left, or training so your team stops depending on us for every change.
n8n consulting for teams building it themselves
The problem, reframed
A lot of n8n instances start as one person's afternoon project and grow into infrastructure the whole business depends on, with nobody ever stepping back to review the architecture against actual production load. That is normal, not a failure. Most teams do not need a full external build; they need someone who has run n8n in production to look at what exists and tell them plainly what to fix before it becomes a real incident.
If what you need is a full workflow built and delivered end to end, our n8n Workflow Automation service covers that directly. This page is for teams who already have the technical capacity to build and maintain their own workflows and want expert review, scaling guidance, or training rather than a build handed to them.
What we build
01
Architecture and scaling review.
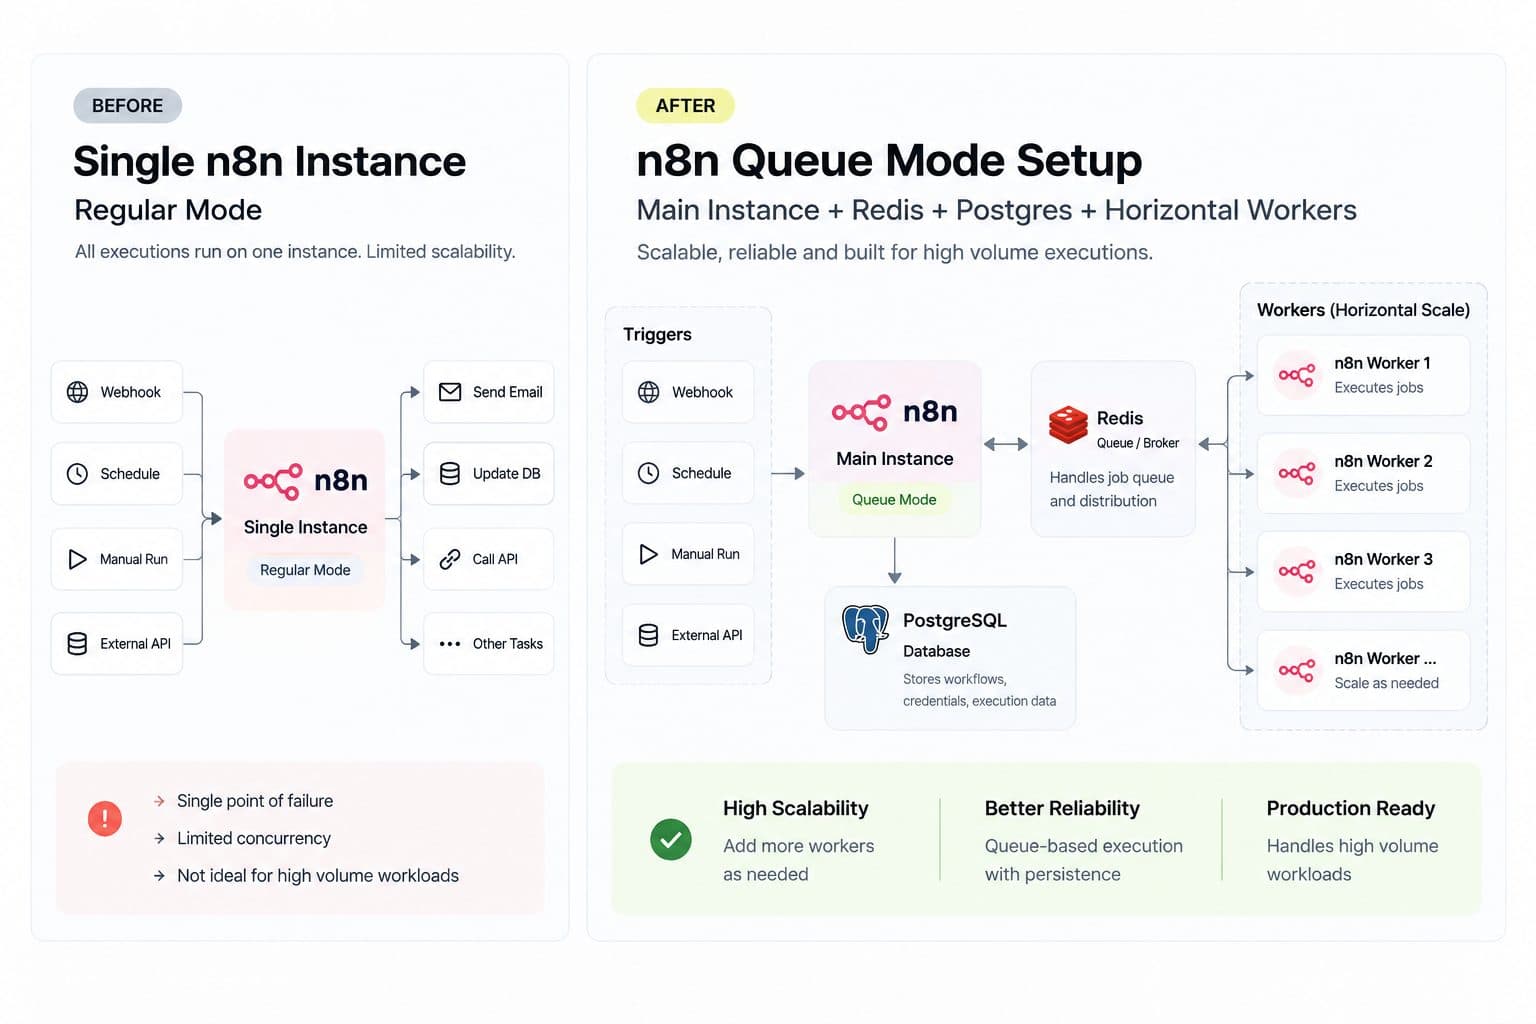
We audit whether your instance is running in regular mode past the point that makes sense; regular mode handles one to ten concurrent executions reasonably before webhooks start queuing behind running jobs; and give a concrete migration path to queue mode: Redis as the job broker, a main instance handling the UI and scheduling, and workers pulling jobs independently so a long-running workflow stops blocking everything else.
02
Database and infrastructure audit.
Queue mode requires PostgreSQL; SQLite does not hold up under concurrent production load. We check whether your credentials and encryption key are stored properly in a secrets manager rather than sitting in a plaintext .env file on a server anyone with SSH access can read.
03
Workflow governance audit.
We review your existing workflow library for the patterns that cause real incidents: error workflows that are not actually configured, credentials shared across more workflows than they should be, and webhook-triggered flows with no rate limiting that will fall over the first time an upstream system sends a burst. You get a prioritized list, not a vague "your automation could be better" writeup.
04
Migration and version strategy.
Guidance on upgrading a pinned n8n version safely, testing in staging before production, and a rollback plan, because an untested upgrade on a workflow instance the whole business depends on is exactly the kind of incident a review like this exists to prevent.
05
Team training.
Hands-on sessions with your own developers covering the patterns that matter in production, not the beginner tutorial content freely available elsewhere: error handling design, credential scoping, sub-workflow structure for anything reused across multiple flows, and when an n8n workflow is the wrong tool for a problem that actually needs custom code.
Recently shipped
Built on our own production instance first. We run a self-hosted n8n instance in queue mode with Redis and PostgreSQL for our own operations: content publishing workflows, client onboarding automations, and internal reporting pipelines. When we review your instance, we are comparing it against what we run ourselves, not a theoretical best-practice checklist. We dogfood the same architecture we recommend.
Built on a modern, connected stack
We run our own production n8n instance, self-hosted, the same way we are recommending for you, not a demo environment we spin up for sales calls. When a client instance needs to talk to Claude API, OpenAI, or a vector store like pgvector for retrieval-heavy workflows, that is architecture we run ourselves daily, not something we are learning alongside you.
Who this is for
01
Teams with in-house developers
who built n8n workflows themselves and want an experienced second opinion before scaling further.
02
Companies inheriting an n8n instance
from someone who left, where nobody currently understands the full workflow library or why certain decisions were made.
03
Growing businesses hitting real load
where regular mode is starting to show cracks and a queue mode migration needs to happen correctly the first time.
04
Teams wanting to build internal n8n capability
rather than staying dependent on an external agency for every workflow change.
Why Flowagenz
Advisory that leaves you more capable, not more dependent.
The engagement is built around your team being able to maintain and extend the instance afterward, not around creating a reason for an ongoing retainer.
Based in Salem, Tamil Nadu.
Western-grade engineering judgment at a rate structure offshore delivery makes possible.
Real overlap, not vague promises.
Async-first communication with working hours that overlap US Eastern mornings, UK afternoons, and Australian business hours on the same day.
We tell you when consulting is the wrong fit.
If the audit turns up a workflow library that genuinely needs a rebuild rather than a review, we say so directly and point you to what that would actually involve, rather than stretching an advisory engagement to cover work it was never scoped for.
How it works
01
01
Instance and access review.
We get read access to your n8n instance, infrastructure, and, where relevant, your deployment pipeline, and review current architecture against your actual execution volume.
02
02
Findings and prioritized recommendations.
A written report covering scaling readiness, governance risks, and infrastructure gaps, ranked by how much production risk each one actually carries.
03
03
Review session with your team.
A live walkthrough of the findings, not just an emailed document, so your developers can ask the questions that matter to them directly.
04
04
Optional training or migration support.
Hands-on sessions or direct support during a queue mode migration if your team wants us alongside for the actual change. Typical engagements run 1 to 3 weeks depending on instance size and workflow count.
What you get on handover
Every n8n consulting engagement ships with the following:
Architecture and scaling review report documenting current mode, execution volume, and queue mode migration path if needed
Database and infrastructure audit covering PostgreSQL readiness, credential storage, and secrets manager configuration
Workflow governance audit with a prioritized list of error handling gaps, credential sharing issues, and rate limiting risks
Migration and version strategy for upgrading n8n safely with staging, rollback, and testing steps
Team training materials covering error handling, credential scoping, sub-workflow patterns, and when custom code is the right choice
Queue mode architecture diagram showing Redis broker, main instance, worker nodes, and PostgreSQL setup
Documentation for maintaining and extending the instance without ongoing dependency on us
Optional hands-on migration support during queue mode cutover if scoped in
30-day post-engagement support for questions on findings, tuning, or implementation
Zero dependency on Flowagenz infrastructure; all recommendations run on your own systems
FAQ
Frequently Asked Questions
Everything you need to know about our process and digital systems.
n8n Workflow Automation is a full build; we design and deliver working workflows for you. Consulting is advisory: we review what you or your team have built, or plan to build, and give you the architecture and governance guidance to do it well yourselves. If a consulting engagement surfaces something that genuinely needs a full build, we will say so and scope that separately.
Book your n8n architecture review
Tell us how your team is currently running n8n and what is prompting the review; scaling concerns, an inherited instance, or wanting to build internal capability. We scope the engagement on a short call and give you a fixed quote before any work starts.